Which AI Privacy Policies are the Most Difficult to Read?
With an average of 4,603 words, these privacy policies are lengthy and contain jargon and technical language that can make them difficult for the average person to read.
With multiple AI policies being considered hard to read by users, how can the most difficult to read be determined?
The Importance of Transparency in AI Policy
Transparency in AI policy is essential for building trust, accountability, and fairness.
Users need to understand how AI systems make decisions, what data they use, and who is responsible when problems may occur.
Clear policies can help prevent discrimination, misuse, and hidden bias while protecting privacy and individual rights.
Transparency also helps governments, companies, and the public evaluate whether AI is being used responsibly.
As AI becomes more influential in society, clear and understandable policies are essential to make sure that technology benefits people while remaining safe, ethical, and accountable.
Many businesses have elected to hire third-party AI consultancy services to keep their AI adoption aligned with business objectives.
Who Writes AI Policy?
AI policy is written by technology companies in collaboration with researchers, legal experts, and international organisations.
Governments create laws and regulations for privacy, safety, copyright, and accountability, while LLM companies develop internal policies on how their systems should be trained and used.
Researchers and AI safety experts will study risks like bias, misinformation, and harmful content, while international organisations may develop their own sets of standards and guidelines.
AI policy usually involves cooperation between these groups.
The Hardest AI Policies to Read by Flesch Reading Ease Score
A Flesch Reading Ease Score is a measure of how easy a passage of English text is to read. It’s based mainly on sentence length and word length.
The score usually runs from 0 to 100, and a higher score means easier reading, while a lower score implies difficulty.
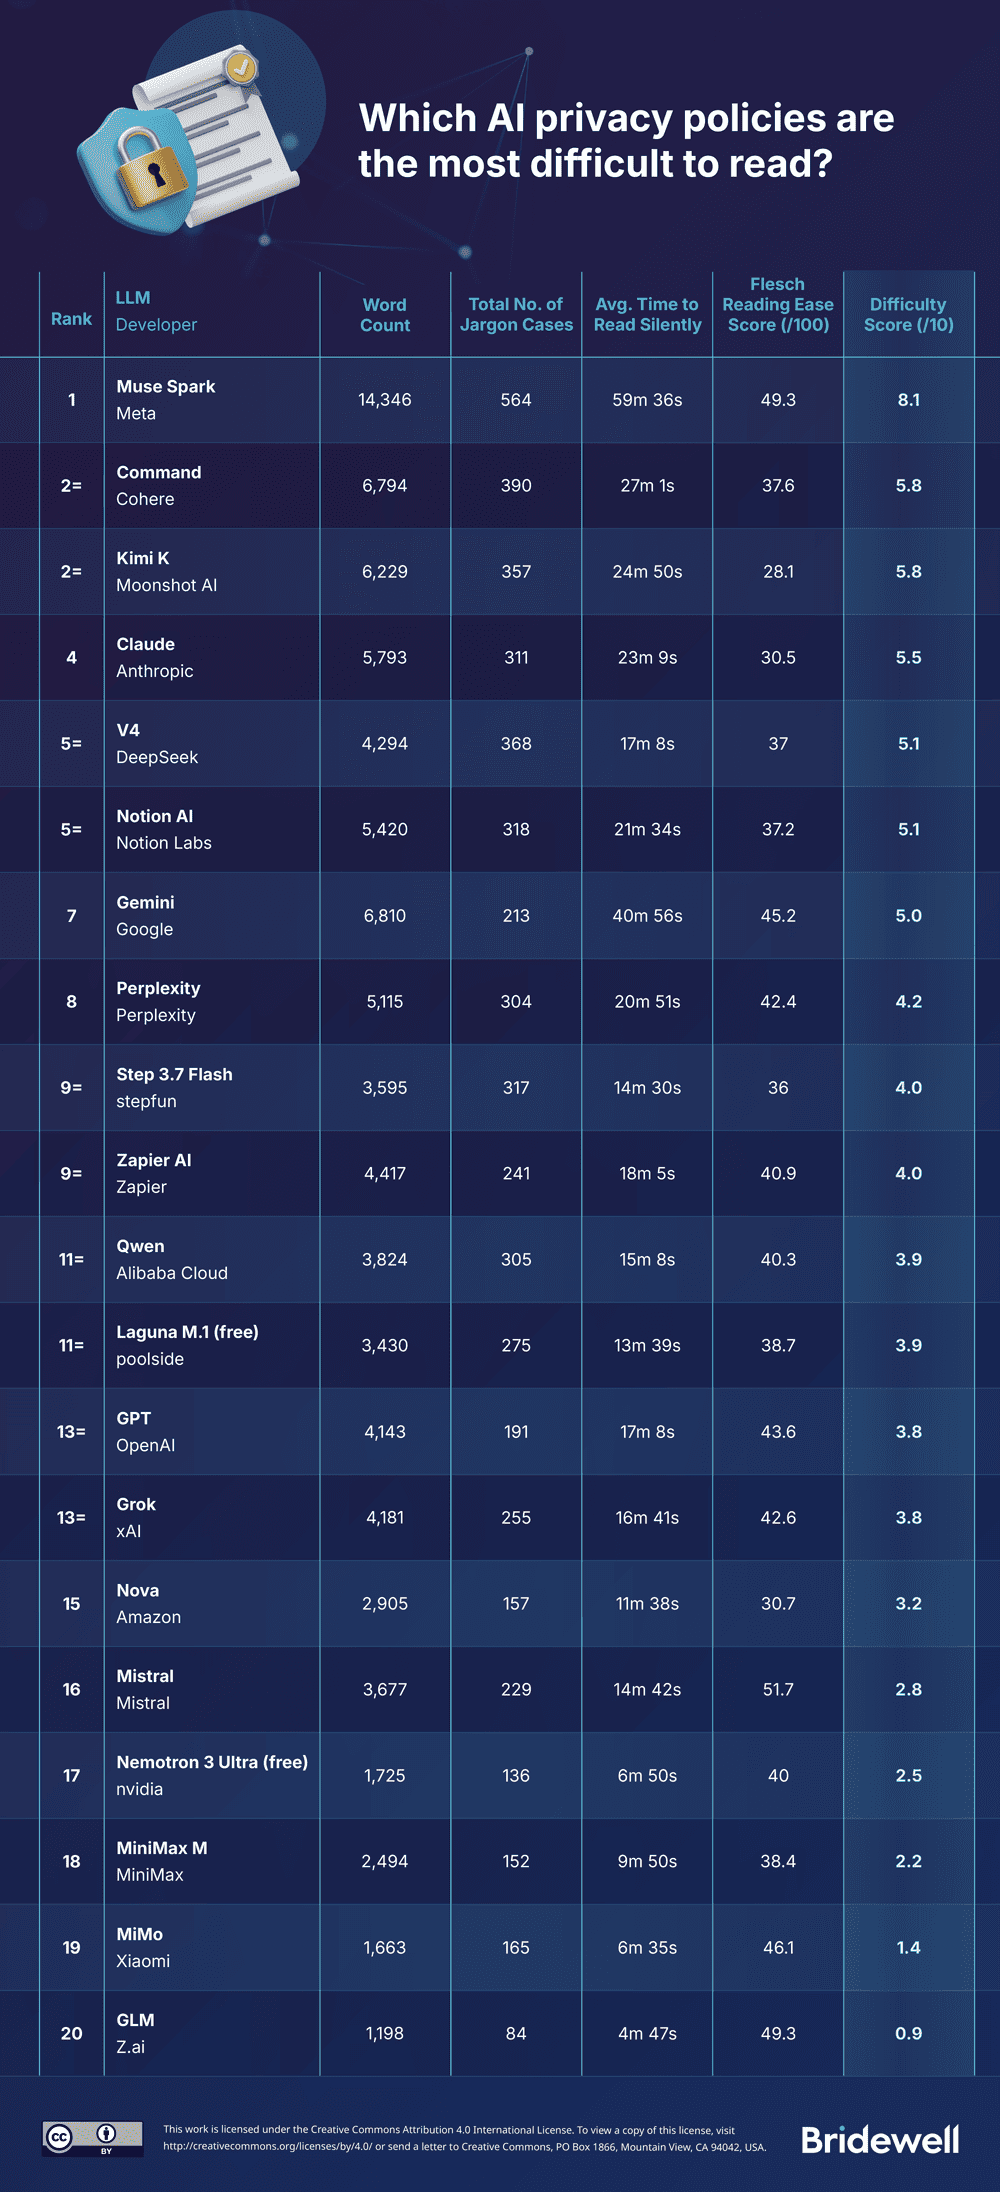
Our data suggests that the three hardest-to-read LLM AI policies are for Moonshot AI’s Kimi K (28.1), Anthropic’s Claude (30.5), and Amazon’s Nova (30.7).
What’s surprising is even incredibly popular LLMs like Claude have a privacy policy with one of the lowest reading scores.
The Flesch Reading Ease Score is a general indicator of how easy a passage of text is to read by eye, but there are additional indicators that further demonstrate is to read conceptually.
The Hardest AI Policies to Read by Time Taken
Time taken to read a passage of text can be a useful indicator of reading difficulty, as harder-to-read text could indicate a dense format and complicated use of language.
Passages formatted in a complicated way can cause readers to slow down or re-read sentences to get their full meaning.
Meta’s Muse Spark has the longest time to read out of any AI policy, taking 59 minutes to read silently, which indicates that its format or language usage are more complicated to read.
Coming in second, with an out-loud reading time of reading time of 40 minutes, is Google’s Gemini.
In third is Command by Cohere, with an average time of 27 minutes to read silently.
Reading Practicality and Jargon
Average sentence length, number of jargon use cases, and the amount of technical jargon can also lead to a higher average reading time. This also factors in formatting. Policies with larger variation, such as including lists and white space, can help readers scan information more quickly.
Deciphering complex wording causes readers to look up unfamiliar words or re-read passages.
The LLM policy with the longest average sentence length is Muse Spark (45.3), which also had the highest total number of jargon use cases (564) and technical jargon (293). However, DeepSeek’s V4 has the highest number of legal jargon use cases at 302.
Tied for first in the most unique jargon use cases (50) were V4, Notion AI by Notion Labs, and Gemini.
The Best and Worst AI Privacy Policies for Readability
When combining these factors, the most difficult AI policy to read is Muse Spark, with a combined difficulty score of 8.1 out of 10. This policy is also noted to be repetitive, making it overly verbose and reducing clarity.
Tied for the second most difficult AI policies to read are Command and Kimi K, both with a difficulty score of 5.8.
The next most difficult policies to read and understand are Claude (5.5), V4 (5.1), and Notion AI (5.1), respectively.
The three LLMs with the easiest AI policy to read are MiniMax M (2.2), MiMo (1.4), and GLM (0.9), with notable LLMs like Grok (3.8) and ChatGPT (3.8) coming in the lower middle of the pack.
The most difficult-to-read LLM policies tend to use longer sentences, use complex legal or technical jargon, and are written in dense paragraphs with fewer plain-language explanations.
This is why LLMs like Muse Spark, Command, Kimi K, Claude, V4, and Notion AI may require a higher reading level in order to decipher their AI policy.
By comparison, LLM policies from GLM, MimMo, and MiniMax M are concise with simpler wording.
How AI Policy Can Affect Your Business
AI policy can affect how your business uses artificial intelligence, handles data, and serves customers.
Regulations, provider policies, and certifications like ISO 42001 can set rules for privacy, security, copyright, transparency, and acceptable use. Businesses that fail to follow these rules could face legal, financial, or reputational risk.
Policy changes may also affect which AI tools you can use and how you can use them.
As a business stakeholder, it’s important to stay informed about AI policy to help your business manage compliance and risks, protect sensitive information, and make better decisions when adopting AI.
Start Your AI Consulting Journey
Speak with one of our consultants to see how Bridewell can support your organization’s AI consulting efforts.
Speak to our AI Consulting Experts
Methodology
The study used Claude and manual checking to investigate the following metrics:
- Word counts
- Average sentence length
- Number of jargon use cases and number of unique cases
- What data they store and how they use it
Other sources were used for the following metrics:
- Readability – https://hemingwayapp.com/readability-checker
- Average time taken to read - https://wordstotime.com/
- Flesch Reading Ease – https://goodcalculators.com/flesch-kincaid-calculator/
Data was then normalised using min-max normalisation, where the value is multiplied by 10 to create a score (between 0-10) and ranked accordingly. A score of 10 marks the most difficult to read, whilst a score of 0 marks the easiest.
Related Information
Bridewell
Insights by Bridewell
 Blogs
 Blogs